Orchestrated Multi-Model AI System

OMMAIS

A local AI workstation. It runs a panel of models on your own hardware, over your own files, and nothing leaves the machine.

Open the workspace Runs on your own Ollama, in this browser. No account.

OMMAIS's Conductor-Expert architecture A request enters at the top and reaches the Conductor, which routes it to whichever expert lanes it needs — science, code or writing. Each lane holds several specialist models. Their answers converge on a synthesis step, which produces the single response returned to the user. REQUEST Conductor SCIENCE CODE WRITING expert expert expert expert expert expert Synthesis ONE ANSWER
One request, routed to the specialists it needs, returned as one answer. Over a hundred expert roles, all running on your own machine.
Which model should I choose? by what your machine can hold

The single number that matters is how much VRAM your graphics card has (or unified memory, on an Apple Silicon Mac). A model has to fit in it to run at a sensible speed. With VRAM optimisation on — it is on by default, in the demo's Settings — only one seat's model is resident at a time, so the figure to compare against is your largest single choice, not the total of all five.

You haveComfortable model sizeExamples to pull
6–8 GB3B–8B, quantised llama3.2:3b, qwen3:8b
12–16 GB8B–14B qwen3:14b, gemma3:12b
24 GB24B–32B qwen3:32b, gemma3:27b
48 GB+ / multi-GPU70B and mixture-of-experts llama3.3:70b, gpt-oss:120b
No dedicated GPU1B–3B, on the CPU llama3.2:1b — slow, but it runs
A phone, via Termux1B–3B, occasionally 8B llama3.2:1b, qwen3:1.7b — 8B only on a recent flagship

Retrieval needs one more, and it is small: ollama pull nomic-embed-text is 274 MB. Without an embedding model the demo's Your files panel has nothing to index with, and reads as broken rather than unconfigured.

Why a panel beats one model

Not because it is more model. Routing the best model to each task caps a panel at the best single model's score on any one question — strengths do not stack. The gain comes from three specific things one model working alone cannot do.

  1. It splits the work. A deliverable bigger than one call's attention — a multi-file program, a long analysis — becomes pieces each seat can actually finish, instead of one answer that thins out towards the end.
  2. It disagrees with itself. Different models fail differently, so when two seats contradict each other the contradiction is information, and a seat whose only job is to adjudicate decides which one to believe. Most of the gain lives here — which is why each of the three expert seats takes a different model, and why the demo tells you when they are all the same. Three copies of one model mostly agree with themselves.
  3. It checks the arithmetic. Before anything reads the experts' work, their stated numbers are compared against each other. Where two seats give values for the same quantity an order of magnitude apart, that is reported as established fact rather than left for a model to notice. A claim checked by something deterministic beats a claim from a better model.

What the mechanisms need from the models

All three depend on something a single model answering a question does not: whether each seat can follow an instruction precisely. A model on its own is mostly limited by what it knows. A pipeline is limited by obedience to a contract — Conductor 1 has to emit briefs in an exact format, the experts have to respect an EXCLUDES clause and stay off each other's territory, the thinking seat has to judge work rather than summarise it, and Conductor 2 has to synthesise instead of concatenating.

Small models fail at those jobs visibly. Run the workspace on a 1B and you will watch Conductor 1 ignore the brief format outright — the interface says so when it happens, and falls back to running the experts on the request directly. That is a worse plan, and the answer is correspondingly worse. The same request through a 30B or a 120B produces briefs that genuinely divide the work, and an answer that reads like one considered piece. This is the honest reading of the claim: the panel is a multiplier on seats that can hold a contract, not a way of making small models behave like large ones.

The screenshot further down this page is the full product on this author's own hardware: three different flagship models in the Conductor 1, OMMAIS and Conductor 2 seats at once, a 262k context window, and a library of 652 documents indexed to 12,630 chunks for retrieval. That is what the ceiling looks like. The workspace is the same shape with the ceiling removed.

What this is not: consensus, averaging, or asking three models and taking the most popular answer — none of which produce any surplus at all. And small models in an ensemble are not inherently safer than one large one; capability is capability. What is true of OMMAIS is that every hop is inspectable, every run can be interrupted, and all of it is yours, on your own hardware.

In development — not yet released

OMMAIS

The next version — in development

A rebuilt OMMAIS: the same local-first idea, with the coding lane, the approval gate and the workspace tools reworked from the ground up. Not released yet — no date promised, because a date promised is a date missed.

  • A Conductor reads the request, decides which specialists it needs and routes to them — pattern matching first, a model only when the patterns are not enough. Their answers are synthesised into one response rather than concatenated.
  • Everything runs on your own hardware. Models are placed across GPUs and CPU according to what will actually fit, recalculated rather than assumed.
  • Documents you add become searchable context, and anything hidden inside one — white text, an OCR layer, an instruction aimed at the model — is indexed as evidence and never promoted to an instruction. Reading is not obeying.
  • File edits arrive as a diff and wait for your approval. The terminal checks commands against a destructive-command denylist and logs what ran. Silence is never consent.
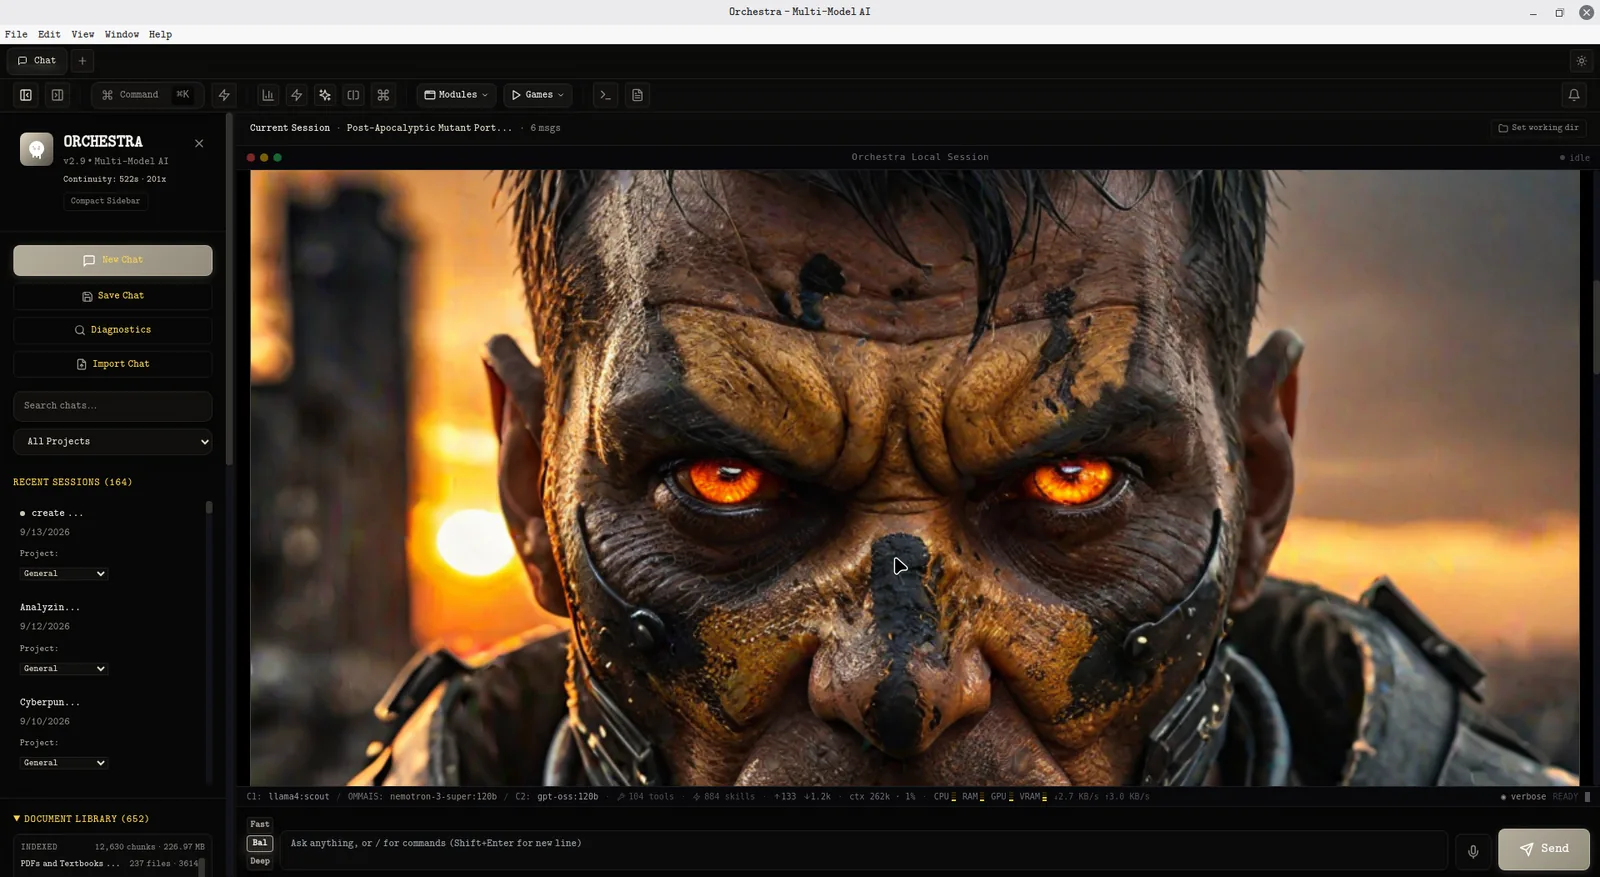
A live session. The sidebar shows 652 documents indexed to 12,630 chunks; the status bar names the seats in use — llama4 on Conductor 1, nemotron-3-super on OMMAIS, gpt-oss on Conductor 2 — with the context window and GPU load beside them.

Nothing to link to yet — no date promised, because a date promised is a date missed.

Available now

OMMAIS Desktop

The current release

The version available today. A local multi-model AI workstation: a panel of models running on your own machine, over your own files, with nothing leaving it.

Get it on GumroadRead the paper

What it does

Local models, coordinated

Several models work a problem together, each on the part it is suited to, instead of one model answering everything alone.

Your files, retrievable

Point it at a folder and its contents become searchable context. Re-index and only what actually changed is read again.

Reads, without obeying

Hidden text in a document is indexed as evidence and never promoted to an instruction. Read is not the same as trust.

Asks before it writes

File edits are proposed as a diff and wait for approval. Silence is never consent. The workspace reproduces the read-and-reason half only: it reads your library and reasons over it, and has no write path at all.

And it ships with games

Not a demo of the AI — these run entirely in your browser, with no model and no server. They are in OMMAIS because building a world is a reasonable thing to want a computer for.

A procedurally generated world. Arrow keys, or the on-screen pad on a phone.